GraphRAG must lead every answer back to the source
An answer is the end of a processing chain. Evidence exists only when that chain can be inspected in reverse all the way to a valid source.
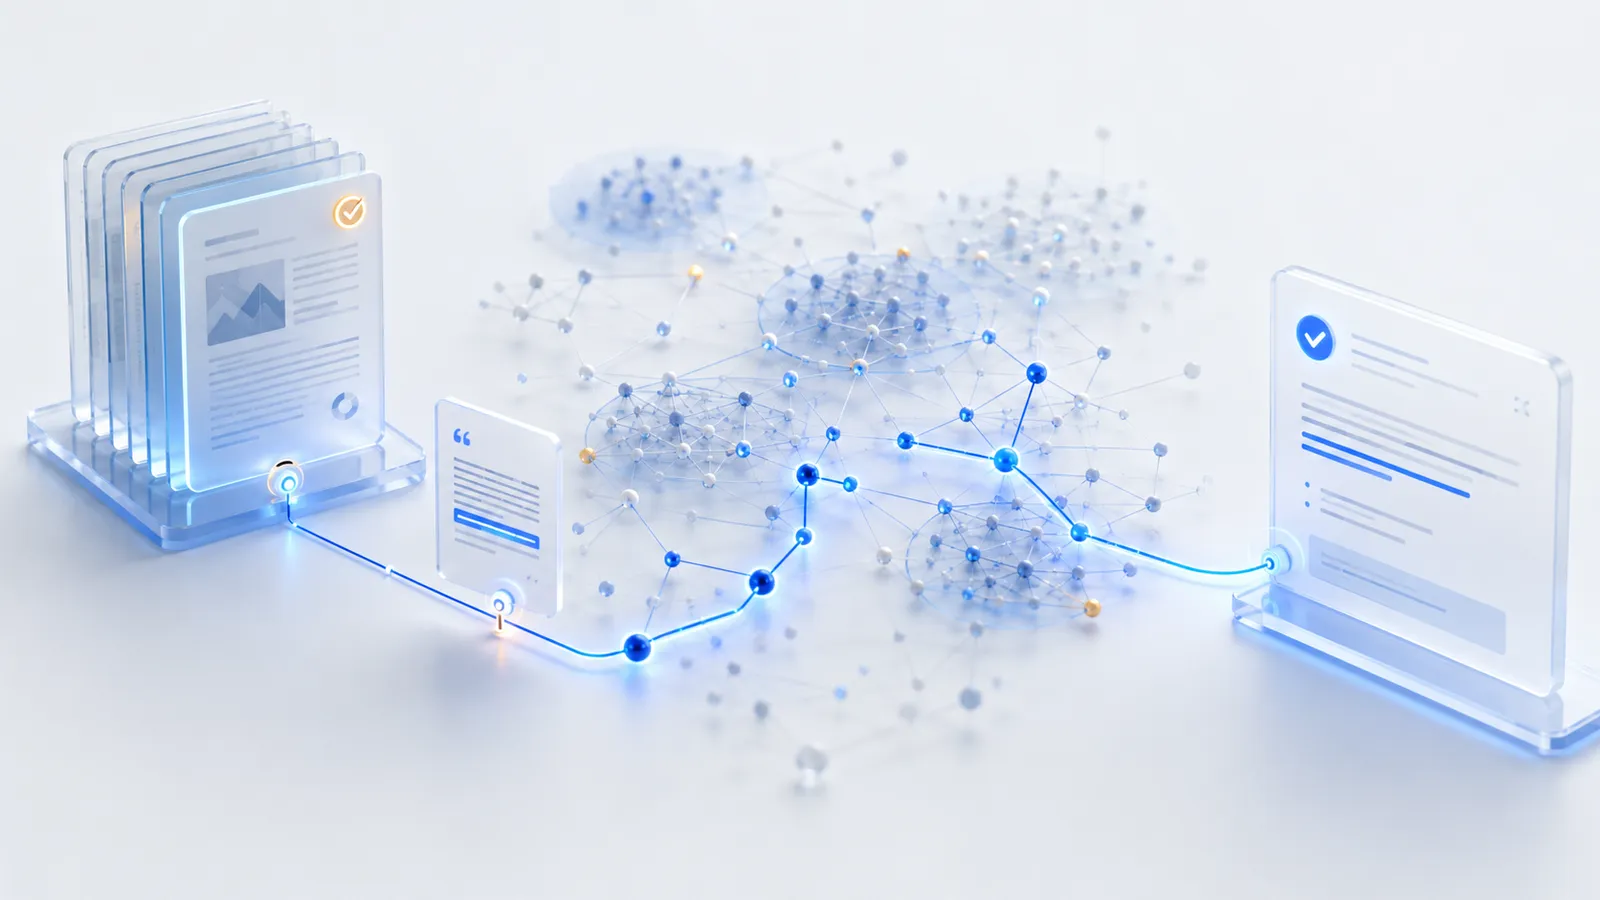
GraphRAG can expose relationships that similarity search handles poorly. Entities connect, communities form, and corpus-wide questions can use a structured representation. This additional abstraction creates a responsibility: every statement must reveal which documents, text units, extractions and summaries produced it.
An impressive graph is not enough. Even clickable citations can be weak when they are merely topical, point to an obsolete version or fail to support the claim. Reliable GraphRAG is therefore not a one-way route from document to answer. It is a reversible evidence path: answer → claim → graph path → relation → text unit → document version → source.
The index is a chain of derived artefacts
The documented GraphRAG architecture produces several layers from raw text. Documents are split into text units. Entities, relationships and sometimes additional claims are extracted. Communities group graph regions and community reports summarise them. Query modes then use different combinations of those artefacts.
Every layer is useful but none is identical to the primary source. Entity labels may be normalised, relationships automatically phrased and reports generated from many passages. Errors can propagate. Each derived object therefore needs stable references to inputs, configuration and creation time. Without them, the index becomes a second knowledge base that may silently drift away from its sources.
Stable identities come before elegant graphs
A source path works only when objects have unique identities. A URL is rarely sufficient: content changes, filenames collide and policies exist in several editions. A robust system separates source, document, version, segment, entity and relationship identifiers.
The document version should be tied to the indexed bytes through a hash or comparable immutable identifier. Metadata should include title, publisher, creation and retrieval dates, language, validity, access scope and superseded versions. An update must not silently overwrite the prior edition. Otherwise the same path appears to remain valid even though its foundation has changed.
Text units need precise anchors
A segment is citable only when it can be found inside the source. Page, section, heading, paragraph or character offsets are possible anchors. HTML may require stable selectors or snapshots. Audio and video need timestamps; OCR should point back to the page image and, where possible, the recognised region.
The visible excerpt must not distort meaning. A sentence may depend on a limitation in the previous paragraph or belong to a counterexample. The system should expose neighbouring passages and document hierarchy. Chunking serves retrieval; it must not define the boundary of proof.
A relationship needs its own provenance
Edges look factual, yet they may come from explicit tables, curated rules, co-occurrence, statistical similarity or automatic extraction. Their origin fundamentally changes their meaning.
A relationship should carry type, direction, scope, extraction method, confidence and supporting passages. Support and conflict from multiple sources must remain distinct. Two passages mentioning the same entities do not demonstrate causation. An edge is a navigable analytical object; referenced passages enable professional judgement.
Entity resolution can improve or destroy the evidence path
Several names may identify one entity, while identical names may refer to different people, products or organisations. Entity resolution joins variants and prevents fragmentation. A false merge, however, connects unrelated sources and creates persuasive but invalid paths.
Alias rules, merge decisions and split corrections must be versioned. Critical identities benefit from human review. The query path should indicate whether identity came directly from a source, was algorithmically inferred or manually confirmed. Reversing a merge and recomputing dependent artefacts is a core architectural capability.
Community reports orient; they do not constitute primary evidence
Global Search uses community reports for corpus-wide questions. This is powerful because abstract prompts provide little direction for a single query vector. Reports, however, compress information that has already been extracted and compressed.
A global answer may have a long derivation chain. It should disclose which reports were considered, how intermediate responses were rated and which source regions ultimately mattered. A report can prioritise a search space, but it is often too distant to support a precise claim alone. Important claims must continue down to text units and original documents.
Local, Global and DRIFT create different evidence distances
Local Search combines graph data with text units around entities. Its source path is often short, although entity resolution and relation extraction can still fail. Global Search uses community reports and map-reduce-style aggregation, increasing evidence distance. DRIFT starts globally and develops local follow-up questions, combining several routes.
These modes need different citation rules. A local factual answer should cite concrete passages. A global synthesis should show covered communities, representative sources and dissenting positions. A DRIFT answer should record its follow-up sequence so reviewers can see why certain graph regions were explored and others discarded.
A link is not yet claim support
Citation quality is not measured by the number of links. Claim coverage matters: which passage truly supports which statement? An answer may list five sources and leave its central claim unsupported. Conversely, one authoritative primary source may be sufficient for a narrow claim.
● Members only
Read the full article and download all files with a membership.
Unlock full article + downloads → Subscribe0 comments
● Loading comments…