Chunking, parsing and the lost connections
A chunk is not merely a piece of text. It is a unit of meaning with provenance, neighbourhood and a role in the document.
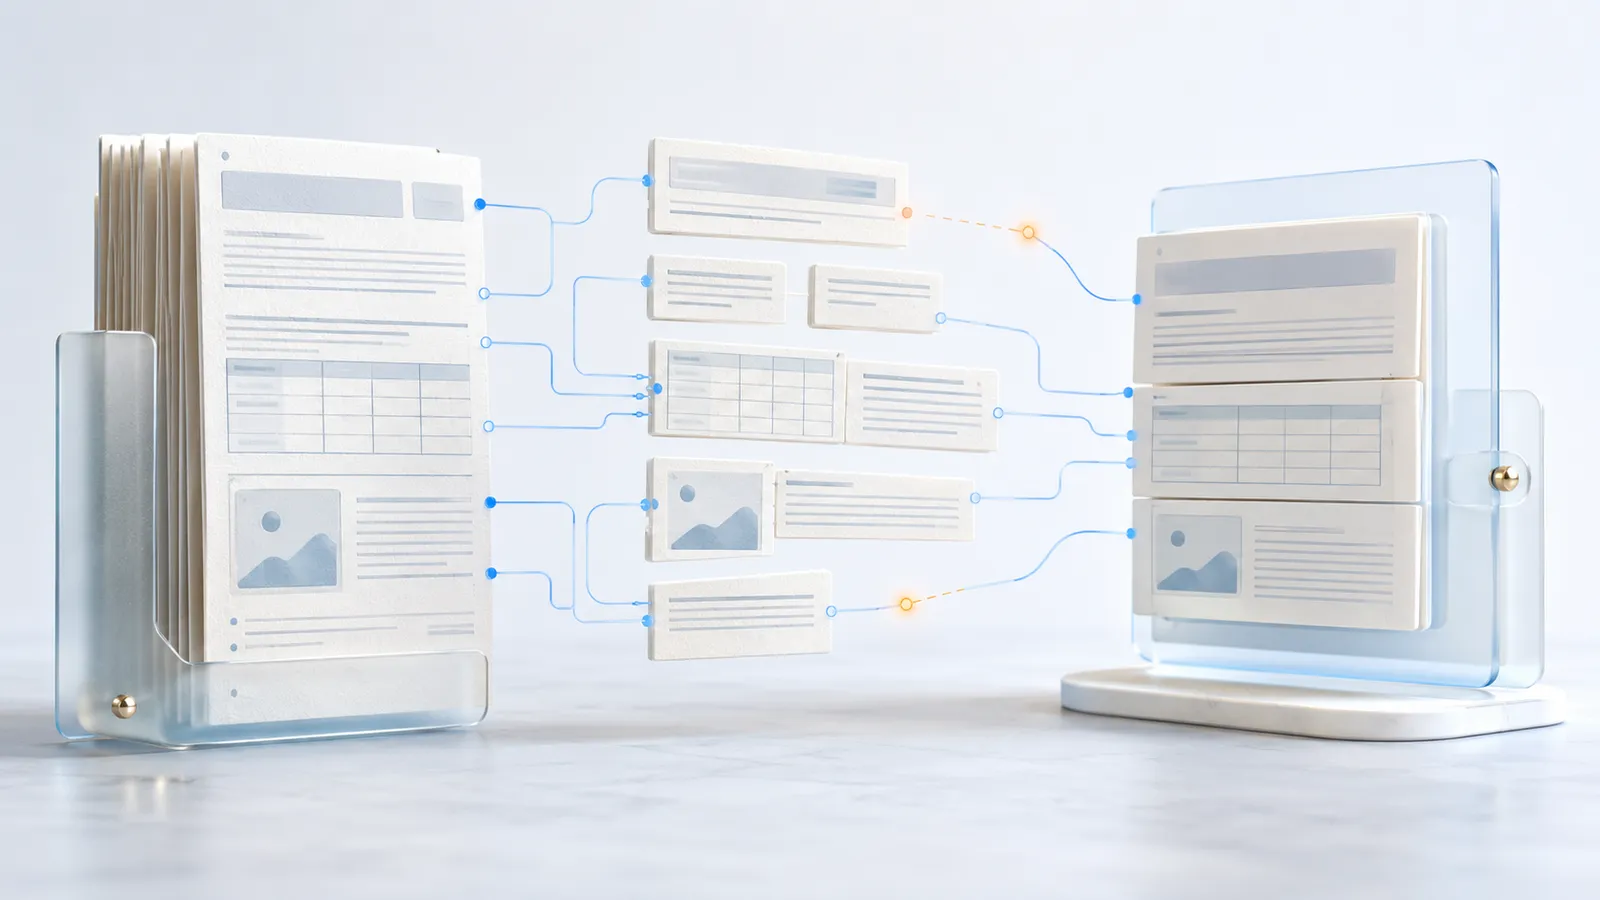
Retrieval systems rarely operate on complete documents. They divide content into smaller units, create representations and later search for relevant segments. The procedure sounds mechanical: extract text, cut at a fixed length, create embeddings and finish. Yet this is where many failures emerge that are later blamed on the language model.
When retrieval returns a table row without its header, an exception without its rule or a caption without its figure, the result is semantically damaged. It may contain similar words while no longer expressing the same claim. Chunking is not a storage optimisation. It determines which knowledge units the system can see, compare and cite.
Parsing comes before chunking
A PDF is initially an arrangement of characters and graphic elements on pages. Visual order does not automatically equal machine-readable reading order. Columns, headers, footers, page numbers, footnotes, callouts, tables and scans can be scrambled by simple extraction.
Parsing reconstructs document structure from layout. It identifies heading levels, paragraphs, lists, tables, figures, captions, footnotes and page references. Scans also require optical character recognition. Only after reconstruction can a system decide defensibly what belongs together.
Parsers can fail: a footer becomes repeated prose, two columns interleave, hyphens are resolved incorrectly or a table collapses into unrelated words. A parser should therefore emit structured elements with type, position, reading order and confidence—not only plain text. Docling describes such an approach with layout analysis and table-structure recognition. The tool is replaceable; the architectural principle is not.
Documents contain several orders at once
A document has linear order, hierarchical organisation and reference relations. A paragraph follows another, belongs beneath a heading and may point to a table three pages later. Plain text preserves only the linear sequence.
Reliable retrieval also needs a path: document → chapter → section → element. Neighbours, cross-references and source version belong with it. „The following exceptions apply" is meaningless without its heading and predecessor. A path such as Security policy → Access control → External accounts → Exceptions exposes the scope.
Fixed windows are a baseline, not a strategy
The simplest segmentation cuts at a fixed number of tokens or characters. It is fast and reproducible but ignores sentence, paragraph and section boundaries. The cut can fall precisely between a rule and its condition.
Small chunks improve topical precision while losing definitions, qualifications and rationale. Large chunks preserve more context but mix subjects, consume the context budget and dilute the relevant passage. There is no universally correct size. A glossary entry, contract clause, table row and method chapter require different segmentation profiles.
Overlap repeats part of one segment in the next. It helps with short arguments but creates duplicates and does not restore structure. Repeating one hundred tokens does not guarantee that a table row receives its column header. A footnote remains ambiguous without its reference anchor. Overlap is a local safety margin, not a substitute for explicit relations.
Tables are small data models
A table cell derives meaning from row and column headers, units, grouping and often a footnote. A segment containing „12 | 18 | 24" cannot reveal whether those values are months, percentages or quantities. A useful table segment includes title, relevant headers, units, row label, values, footnotes and source location.
Large tables may be divided into row groups, but every child links to a parent representing the full table. A structured data representation may be better than text for trend questions. Likewise, caption, figure ID and explanatory paragraph remain linked even when stored separately.
Cross-references create hidden dependencies
Phrases such as „as described above", „these values" or „it does not apply to" point elsewhere. A segment can be grammatically complete while its referent has vanished. A context packet may therefore contain a small primary chunk, section path, short parent summary and selectively resolved references.
Parent-child models separate search from answer granularity. Small children are easy to retrieve; a hit triggers controlled loading of a larger parent or defined neighbourhood. This is often more robust than making every chunk large from the outset.
Semantic and hierarchical methods
Semantic chunking places boundaries where the topic appears to change. It may outperform rigid windows in prose but does not always recognise formal relations. A robust strategy combines hard structural boundaries with soft semantic signals.
Late Chunking first processes a broader context and only then produces representations for subregions. Chunk embeddings can consequently carry information from surrounding text. This is promising but not a universal repair: broken reading order, table structure or missing versions remain broken.
RAPTOR recursively summarises and organises content in a tree so retrieval can operate at several abstraction levels. Detail segments and higher-level syntheses may be indexed together, but they remain different evidence types. A summary is not a primary source; final claims should return to underlying passages.
A large context window does not remove the problem. Research on the „Lost in the Middle" effect reports that models can use relevant information less effectively depending on its position in a long input. More context is not automatically better context. Selection, ordering and emphasis remain engineering tasks.
Extraction is not understanding
The first processing stage makes content technically accessible. Text can be extracted from digital PDFs, while scans require optical character recognition. Tables, columns, footnotes, headings and reading order must be preserved or reconstructed. A plausible stream of text does not prove that document structure was captured correctly.
Quality therefore starts with testable extraction attributes: page reference, detected document type, language, OCR confidence, table count and warnings for unreadable regions. For critical sources, extracted text should link back to the visual source page. An error can then be traced from an answer to a passage and finally to the scan.
● Members only
Read the full article and download all files with a membership.
Unlock full article + downloads → Subscribe0 comments
● Loading comments…