Who owns the data spaces of AI?
A data space rarely belongs to one party. It becomes governable when every data product has explicit decision rights, access conditions, permitted purposes, evidence and a tested route for every participant to leave.
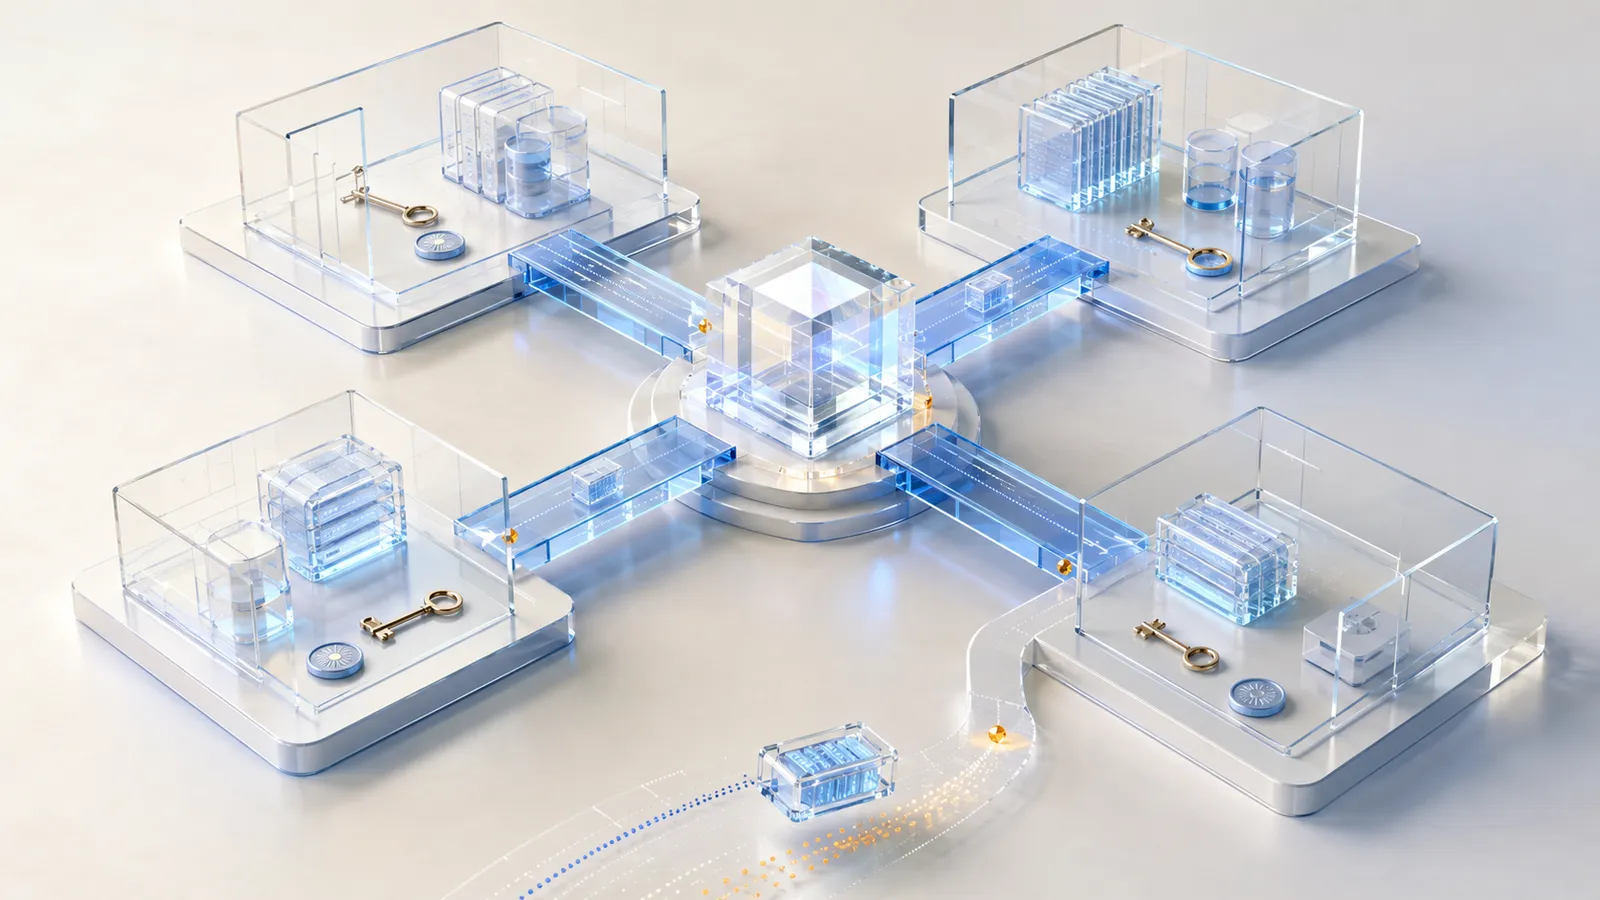
AI does not emerge from a model alone. It depends on sources, catalogues, interfaces, identities, contracts, features, vectors, logs and derived products. Once several organisations participate, „Where is the data stored?" is insufficient. Location says little about lawful authority, technical control or economic benefit.
„Who owns the data space?" is deliberately uncomfortable because ownership is too coarse as a single category. Data can be copied, combined and used concurrently. Personal data is not a physical object owned like a desk. Trade secrets, copyright, database investment, contracts and statutory access claims may shape the same collection differently.
A dependable data space replaces the search for one owner with a map of rights, duties, control and accountability.
Federation, not one central repository
A data space is not merely a very large data lake. In a federated architecture, datasets may remain with providers. Shared identities, catalogues, contracts, policy rules and trust services make them discoverable and conditionally usable. Exchange may occur through download, API, secure processing, query or derived result.
A catalogue entry is not access; access is not unrestricted use; technical transfer is not a legal basis. A platform does not automatically own every payload because it mediates metadata or transactions.
Federation distributes power but does not remove it. Whoever admits identities, sets standards, validates policies, ranks catalogue results or excludes participants controls essential parts of the space. Governance must therefore constrain common-service operators as well as data users.
Seven questions are better than ownership
For each data product, ask separately:
1 · Origin: who or what generated, collected or derived it?
2 · Legal position: which rights, duties, interests and legal bases apply?
3 · Decision authority: who sets purpose, recipients, duration and conditions?
4 · Technical control: who operates storage, keys, identities, policies and logs?
5 · Use scope: which actions are permitted, prohibited or conditional?
6 · Value distribution: who bears cost, receives payment and benefits from derivatives?
7 · Exit: how are data, metadata, provenance and models ported, returned or deleted?
Answers may identify different actors. A provider controls a dataset, a person retains privacy rights, an operator processes on instructions, a consumer gets purpose-limited access and a regulator may inspect.
Do not collapse different data layers
An AI data space contains raw records, curated datasets, metadata, embeddings, features, training and evaluation sets, parameters, prompts, outputs, feedback, logs and usage statistics. Each layer has its own origin and risk.
An embedding is not automatically anonymous because people cannot read it. A derived score may be personal data when it relates to an identified or identifiable person. Synthetic data can reveal source information or inherit restrictions. A model may memorise training content without being a copy of the dataset.
Every data product therefore needs a manifest: type, source, period, version, transformation chain, personal-data status, protection class, quality limits, permitted purpose, prohibited use, retention and deletion route.
Access is not the same as use
A partner may inspect a dataset but lack permission to train a model. It may analyse but not redistribute; produce aggregates but not export individual values; process for a contract but not retain data for product improvement.
These limits belong in testable policies, roles and technical gates as well as contracts. Machine-readable policy models can express permissions, prohibitions, duties and constraints. They do not replace legal analysis but connect agreed terms to execution.
An access token therefore references dataset ID, version, purpose, operation, recipient, expiry and onward-sharing rule. A new purpose requires a new review. „Data-space access" must never become a general mandate.
The catalogue is a constitutional layer
Without shared metadata, a federated space is invisible. A catalogue describes datasets and services, publishers, themes, interfaces, coverage, versions and access conditions. Standards such as DCAT support federated search and catalogue exchange.
Claims must remain evidenced. Quality statements specify measurement and date. Availability, freshness and licence are versioned. A changed policy cannot circulate indefinitely under an undifferentiated identifier.
Search and ranking are governance issues. Preferential ordering or exposure of sensitive attributes changes market access and risk. Criteria and conflicts of interest should be transparent.
Identity and trust remain verifiable
Participants need more than credentials. The space verifies organisation, role, representation authority and relevant attestations. Trust anchors confirm claims but do not guarantee every transaction. A correctly identified participant can still misuse data.
Onboarding covers identity, policy acceptance, technical checks, minimum safeguards and contacts. Offboarding revokes tokens, ends transfers, resolves retention duties and preserves evidence. Forgotten service accounts must not retain access.
Provenance connects source, use and result
AI lengthens data chains. An output may combine documents, tables, sensor values, retrieval results and human corrections. Without provenance, teams cannot determine which source influenced a statement, decision or model change.
A provenance graph references entities, activities and accountable agents. It records which dataset version entered which process and artefact. Sensitive payload need not be copied into the log; stable IDs, hashes and protected references often suffice.
Provenance supports payment, quality correction, deletion impact and disputes. If a source is withdrawn or found defective, the graph identifies products requiring reassessment.
● Members only
Read the full article and download all files with a membership.
Unlock full article + downloads → Subscribe0 comments
● Loading comments…